Qwen Code Workflows: Choosing Interactive or Batch AI Tasks
AI-assisted original analysis: use four questions and a small paper exercise to choose a work mode, define useful outputs and catch errors before scaling up.
Start with the shape of the work
A useful AI workflow starts with a clear unit of work. Before choosing a tool, describe what goes in, what should come out, and what evidence would let someone accept the result. A familiar interface can hide a badly defined task; a precise task is easier to inspect in any interface.
The October 9 Qwen update ↗ describes Mac/Linux browser support; Windows is unsupported. Independent single-pass jobs can use batch processing after plan review and explicit confirmation.
The following classification exercise is our own proposal. It has not been benchmarked, and it does not require submitting a job.
Four questions before you choose a mode
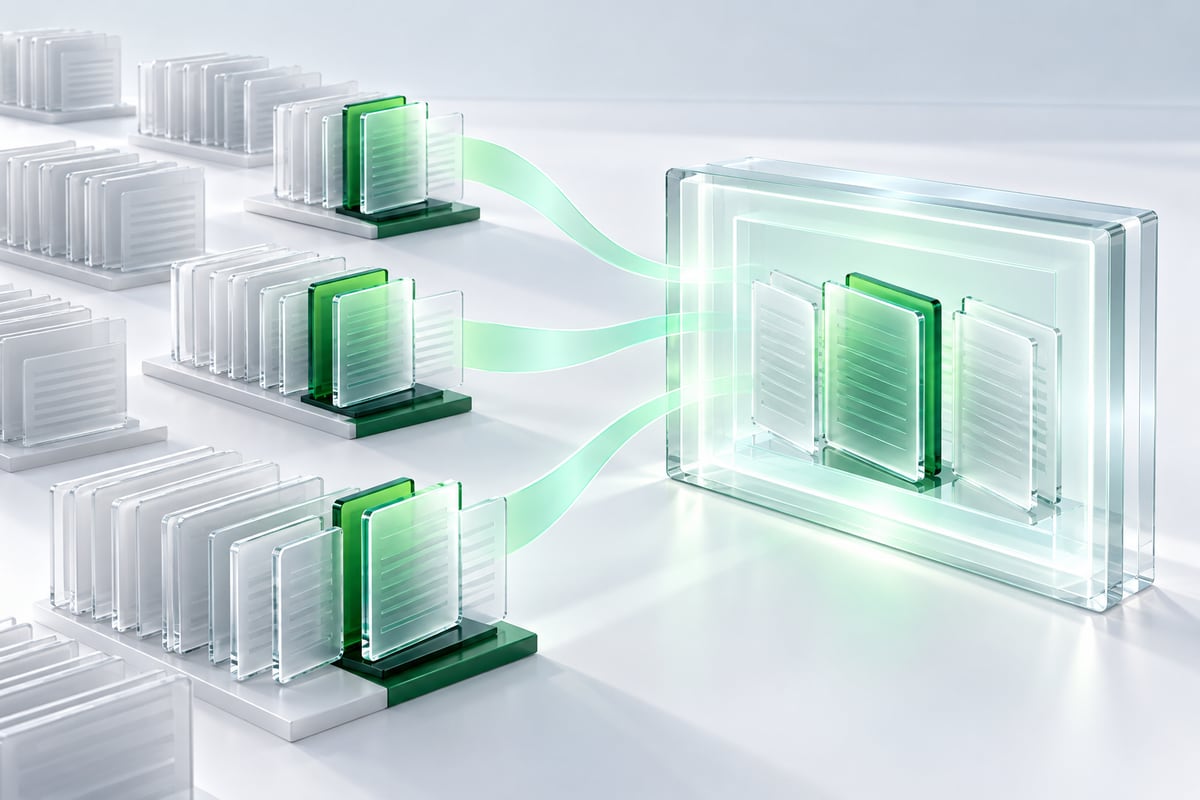
First, can the input stay fixed while the work runs? A changing design brief or an investigation that needs the next answer to decide the next step calls for an interactive session. A folder of approved inputs can be considered for a batch after their boundaries are explicit.
Second, what would count as a correct output? “Improve these reports” leaves the reviewer guessing. “Return the report ID, one category from this list, and the supporting sentence” gives both the model and the reviewer something concrete to check. For a creative task, describe the intended audience and the criteria for selecting a draft.
Third, does one item depend on another? Several files can form one investigation. Splitting them into separate requests may remove the relationship you need to understand. Keep dependent items together; independent items can be evaluated separately.
Fourth, when must a useful answer arrive? Write a latest acceptable delivery time. This exposes whether waiting is compatible with the task, before anyone optimizes throughput or price.
A twelve-item paper exercise
Invent twelve short bug reports, each with an ID, a symptom and two lines of context. Decide on three labels: display, interaction and performance. Leave two reports deliberately ambiguous. Your target output is a small record containing the same ID, a label, a supporting phrase and a review-needed flag.
Sort these four jobs:
- Classifying the twelve fixed reports: a batch candidate after the sample passes review.
- Investigating a button that sometimes responds twice: interactive, because the next observation may change the diagnosis.
- Agreeing on the three labels with a teammate: a short discussion before processing any reports.
- Renaming files under an exact, complete rule: consider a small deterministic script.
Write down your reasoning beside each choice. The purpose is to reveal assumptions, including cases where an AI request adds little value.
Put a check between two steps
- Define
Input and acceptance criteria
- Produce
One inspectable unit
- Verify
Behavior and evidence
- Decide
Accept or revise
Make acceptance visible
Review three invented reports first. Check that each output preserves its ID, uses an allowed label and cites a phrase actually present in the input. Check whether uncertainty is visible for ambiguous examples. These are suggested acceptance checks, not a claim that the tool will satisfy them.
For the complete exercise, reconcile input and output IDs. A missing result, duplicate result or unsupported explanation belongs in a review queue. Record which item needs correction and why; a successful-looking total can hide a failed item. Keep the original inputs and inspect revisions separately so a retry has a clear scope.
Limits and a next step
Task classification cannot promise correctness, cost savings or unattended execution. Someone still owns access decisions, acceptance criteria and the choice to submit or retry. The official batch reference ↗ is the place to verify the current configuration and submission behavior before a real run.
Try the exercise on paper today. If you cannot explain why an output is acceptable, improve the task definition and the checks before increasing the number of items.
Understand it. Then try it.
Read something elseNo sign-in needed. One like per browser, across all languages.
Original references
Use these links to verify details and learn more. A reference does not imply endorsement.
qwenlm.github.ioReference 1qwenlm.github.ioReference 2